As businesses deploy autonomous AI agents that make decisions, call external tools, and execute multi-step workflows, detecting unexpected behavior before it causes operational problems has become a critical engineering challenge. AI agent monitoring helps teams track agent execution, while behavioral anomaly detection identifies deviations from expected behavior that conventional application monitoring may miss. Together, these capabilities support AI agent reliability by helping engineering teams identify, investigate, and address failures in production environments.
What tools detect unexpected behavior in AI agents? The answer includes AI agent observability platforms, execution-tracing systems, behavioral anomaly detection tools, and evaluation frameworks that examine how agents behave throughout a task. Unlike conventional application monitoring, which primarily tracks system health, latency, and errors, these tools can help identify incorrect decisions, abnormal tool-call sequences, repetitive actions, and deviations from an intended workflow, even when an agent reports successful execution.
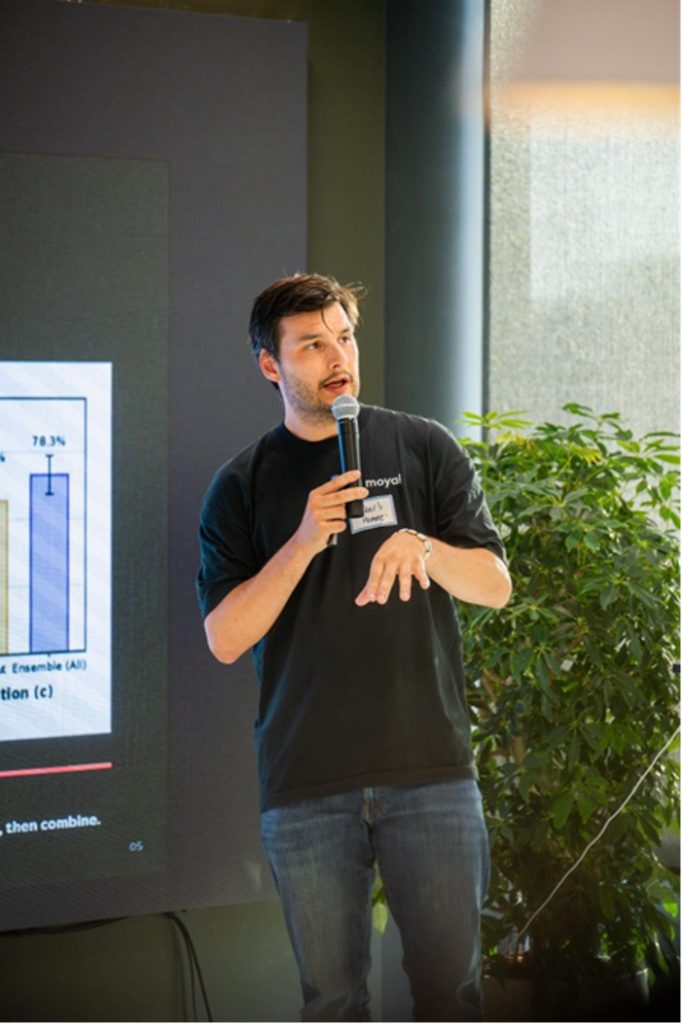
Table of Contents
Why Traditional Monitoring Cannot Reliably Detect AI Agent Failures
Traditional software typically follows predefined execution paths, whereas autonomous AI agents can take different paths to complete the same task. During execution, an AI agent may interpret an objective, generate a plan, make multiple tool calls, process external results, revise its decisions, and repeat these steps until it determines that the task is complete. Monitoring this execution trajectory, including the sequence of decisions and tool interactions, is essential to understanding whether the agent is operating as intended.
This creates a distinct category of production failure: an AI agent can complete a request without generating an application error, yet still produce an incorrect or unsafe result. Examples include hallucinating information, selecting an inappropriate tool, repeating API calls, deviating from an intended workflow, or returning an answer that appears credible but is factually incorrect. Research from Microsoft on the AgentRx framework highlights the challenges of debugging AI agents whose execution trajectories involve multiple steps, variable decisions, and complex tool interactions. These failures demonstrate why successful task completion is not, by itself, a reliable measure of agent performance.
Effective AI agent observability therefore requires more than uptime, latency, and error-rate monitoring. It involves examining agent execution traces, tool-call sequences, intermediate decisions, and final outcomes to identify deviations from expected behavior. This broader view helps engineering teams investigate not only whether an agent failed, but also where its execution diverged and what may have caused the failure.
How Behavioral Anomaly Detection Identifies AI Agent Failures
AI agent monitoring and AI agent reliability address related but different questions. Monitoring tracks whether an agent is running and how it performs, while reliability evaluation examines whether its decisions, tool calls, and outputs remain consistent with expected behavior. AI observability connects these perspectives by providing the execution data needed to investigate deviations and assess whether they represent genuine failures.
Behavioral anomaly detection helps identify AI agent failures that predefined error rules may not capture. Depending on the monitoring approach, a system can compare an agent’s execution against expected workflows, established behavioral patterns, or evaluation criteria. Potential anomalies include unusual tool-call sequences, repetitive API requests, unexpected execution loops, abnormal task duration, and actions that deviate from an agent’s intended workflow. Detecting these patterns gives engineering teams a basis for further evaluation rather than treating every deviation as a confirmed failure.
Silent failures are particularly difficult to detect because they may not trigger conventional monitoring alerts. An agent can use functioning APIs, maintain normal response times, and return a completed result while making an incorrect decision. Behavioral monitoring helps address this gap by examining what the agent did during execution, rather than relying exclusively on infrastructure health or application-level errors.
Research on AI agent reliability provides further context for the challenges that can emerge during extended autonomous execution, including operational hallucinations and repetitive tool calls. These examples illustrate why reliability evaluations need to consider an agent’s behavior over the course of a task, not just the quality of its final response.
AI Agent Reliability Infrastructure: Monitoring, Evaluation, and Failure Detection
As businesses deploy AI agents across customer service, software development, business operations, and enterprise workflows, production reliability becomes an increasingly important engineering requirement. Teams need visibility into an agent’s execution path, tool usage, intermediate decisions, and final output to determine whether a task was completed correctly and within expected operational boundaries. This requires monitoring, behavioral evaluation, and failure investigation to work together rather than treating successful execution as proof of reliability.
One company working in this area is Moyai, an AI agent reliability company co-founded by Robert Hommes. Moyai focuses on monitoring AI agents in production, detecting behavioral anomalies, evaluating potential failures, and helping engineering teams investigate unexpected agent behavior. Its approach addresses a specific challenge in AI observability: distinguishing unusual execution patterns from genuine reliability problems that require attention.
Moyai approaches AI agent reliability as an operational discipline that extends beyond basic uptime monitoring. Its stated approach includes clustering related problems, evaluating potential failures, and alerting teams to abnormal behavior so engineers can investigate issues in production. This reflects the application of site reliability engineering (SRE) principles to autonomous AI systems, where understanding execution behavior is necessary alongside monitoring service availability and performance.
AI Agent Root-Cause Analysis: From Anomaly Detection to Resolution
Effective AI agent monitoring must connect anomaly detection with root-cause analysis. Once an unusual behavior has been identified, engineering teams need to investigate whether it originated in a model response, an incorrect tool call, a workflow decision, an external dependency, or a policy violation. Examining execution traces and related evaluation results can help narrow down the source of the problem and determine what corrective action may be required.
An AI agent reliability platform can help organizations manage these challenges as autonomous systems move from prototypes into production. By combining behavioral monitoring, anomaly detection, evaluation, and failure investigation, these platforms can give engineering teams greater visibility into how agents operate and where intervention may be needed. The objective is not to eliminate autonomy, but to make agent behavior more observable, measurable, and accountable.
For Robert Hommes and Moyai, the challenge of production AI reliability centers on helping businesses understand and evaluate how their AI agents behave in real operating environments. As autonomous systems take on more complex tasks, detecting hallucinations, repetitive tool calls, workflow deviations, and other silent failures will require more than checking whether a system is online. AI agent monitoring and behavioral anomaly detection will increasingly need to establish whether an agent’s execution remains consistent with its intended purpose and operational requirements.
Frequently Asked Questions
What is AI agent behavioral anomaly detection?
AI agent behavioral anomaly detection is the process of identifying deviations from expected agent behavior during execution. Depending on the system, it can involve examining tool-call sequences, execution traces, task duration, workflow decisions, and other signals that may indicate a reliability problem.
How is AI agent monitoring different from traditional application monitoring?
Traditional application monitoring primarily tracks system health, performance, and errors. AI agent monitoring also examines how an agent behaves while completing a task, helping teams identify incorrect decisions, repetitive tool calls, unexpected workflow deviations, and other failures that may occur without a conventional application error.
How do AI agent reliability platforms help businesses?
AI agent reliability platforms help engineering teams monitor production behavior, identify potential anomalies, evaluate failures, and investigate their causes. The specific capabilities vary by platform, but the objective is to improve visibility into autonomous systems and help teams manage operational risk.
What should businesses look for in an AI agent reliability platform?
Businesses should evaluate whether a platform supports execution tracing, behavioral anomaly detection, failure evaluation, alerting, and root-cause investigation. Integration with existing observability systems, the ability to distinguish meaningful anomalies from expected variation, and the clarity of its diagnostic information are also relevant considerations.